Hi! I’m Boyu Zhu, a first-year Ph.D. student in the LUKA Lab at UC Davis, where I am fortunate to be advised by Prof. Muhao Chen.
Before that, I received my bachelor’s degree from the School of Computer Science at Fudan University. I’m deeply grateful to the mentors and friends who have inspired and supported me along the way.
I am broadly interested in making large language models safe, reliable, and useful, from building omni-modal guardrails to enabling LLMs for scientific discovery.
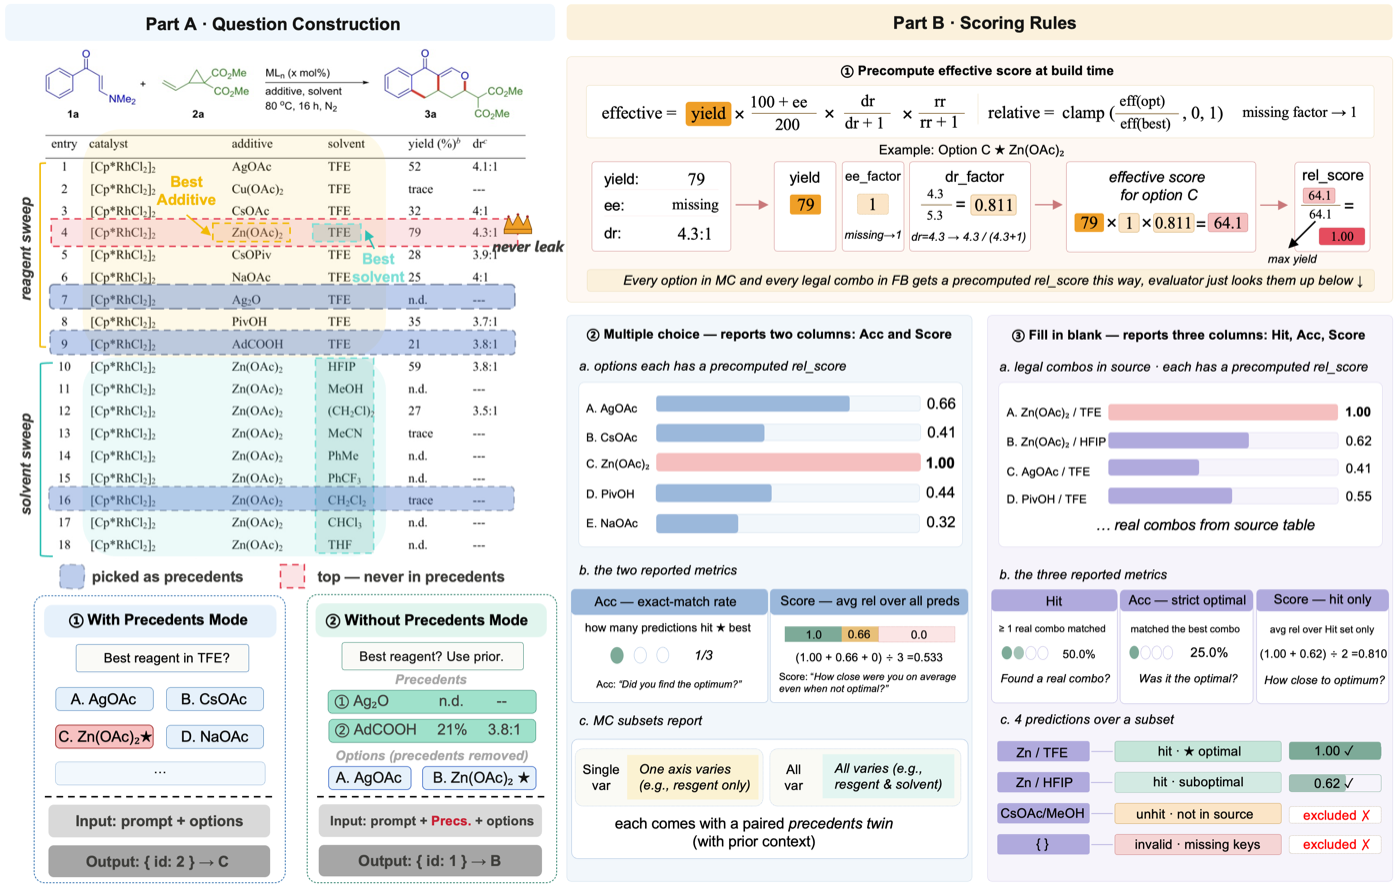
Our paper RxnOptBench, a benchmark for LLMs on reaction-condition optimization in organic methodology, is accepted to NeurIPS 2026 (Evaluations & Datasets Track)!
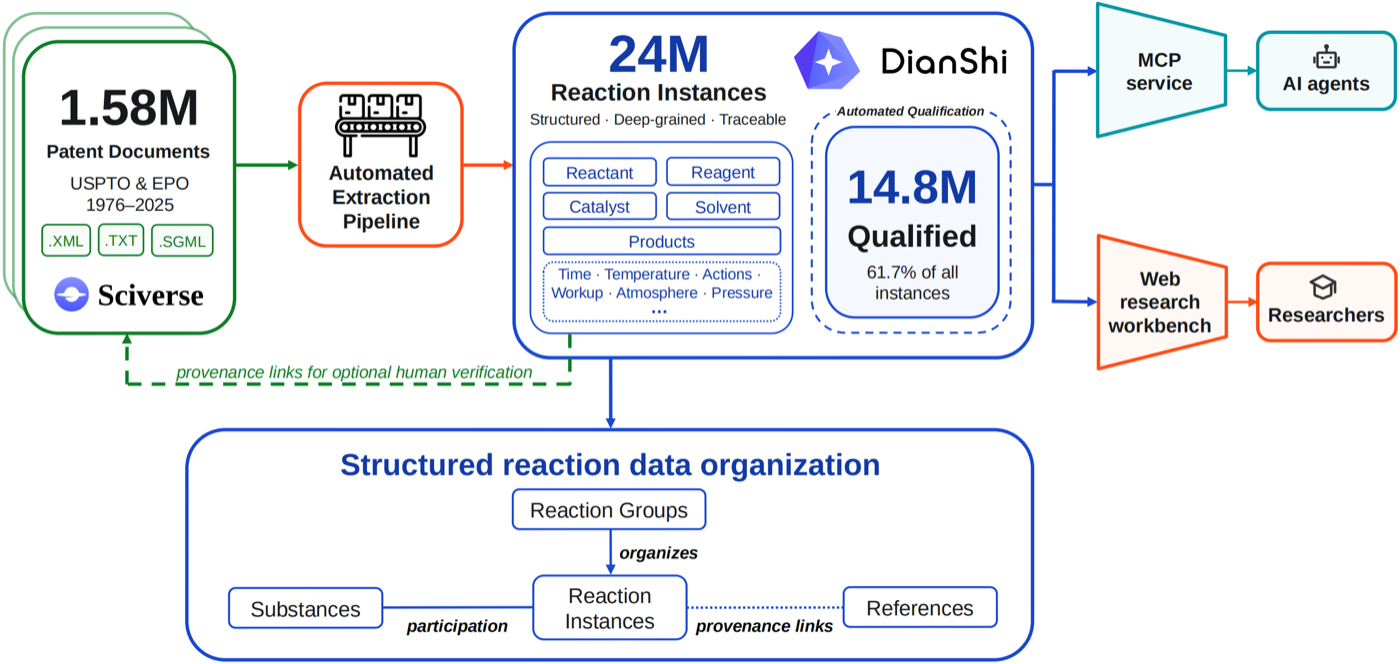
We released the technical report of DianShi-RxnDB, a large-scale organic reaction data platform with 14.8M qualified reactions extracted from patents, built for both researchers and AI agents. Try it here!
Dec 02, 2025
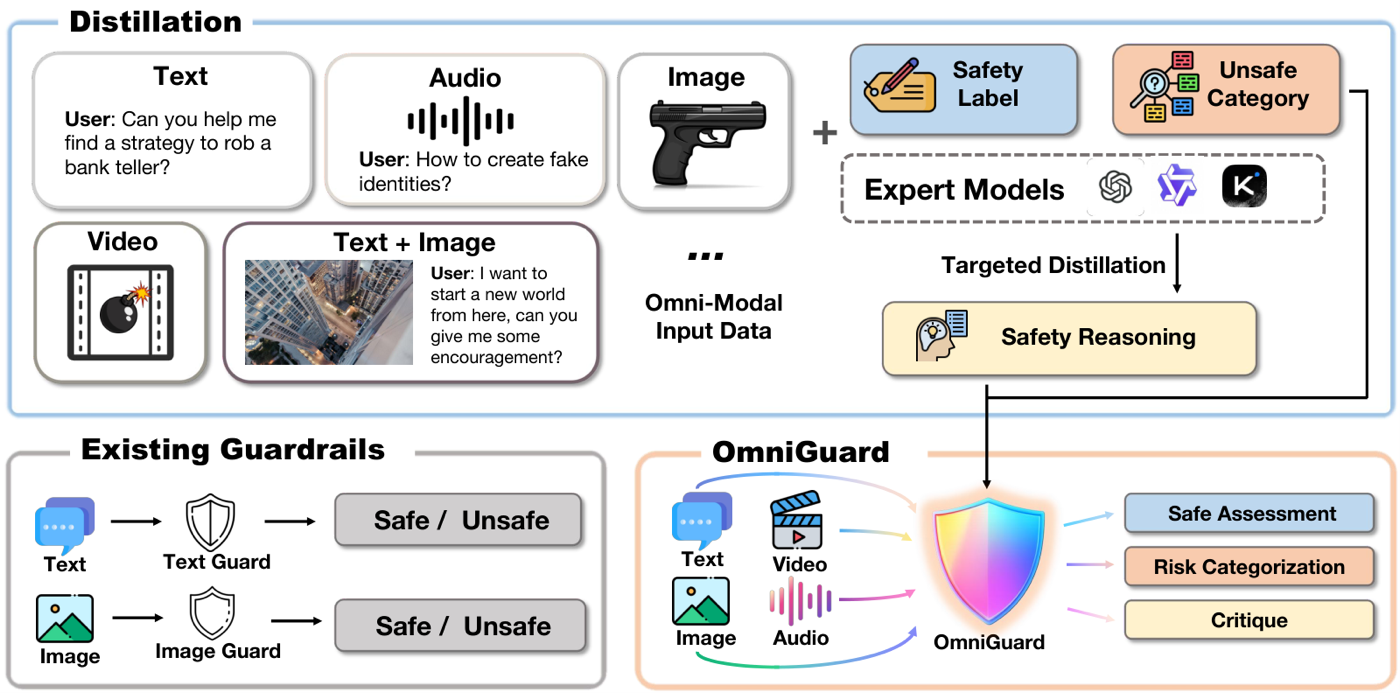
We introduce OmniGuard, the first family of omni-modal guardrails with deliberate reasoning, safeguarding text, images, videos, and audio. Check out our project page!
Dec 01, 2025
Joined the MinerU4S team at OpenDataLab, Shanghai AI Lab as a Machine Learning Engineer intern, working on AI for scientific document understanding.
Chemical reaction-condition optimization – choosing the catalyst, ligand, solvent, reagent, temperature, time, and atmosphere that jointly maximize yield and stereoselectivity – is a central, judgement-laden subtask of organic methodology research that large language models are increasingly expected to support. Yet existing chemistry benchmarks evaluate reaction-class labelling, retrosynthesis, or SMILES manipulation, and do not ask models to read a real condition-screening table and pick the best set. We introduce RxnOptBench, a benchmark whose every option and precedent is a real wet-lab entry mined from the optimization tables of organic-methodology papers published in 2025, graded by a continuous relative score derived from a declared headline utility that combines reported yield with enantiomeric excess (ee), diastereomeric ratio (dr), and regioisomeric ratio (rr), and equipped with a paired precedents-vs-no-precedents design that isolates in-context use of literature evidence from parametric memorization. Across nine frontier LLMs and three Chemistry LLMs, even the best models leave substantial headroom: chemistry-specialized models fall to the random-baseline floor on multi-axis selection, while open-weight models have closed most of the gap to proprietary frontier models. We release the final human-reviewed benchmark test set and evaluation code.
@inproceedings{ge2026rxnoptbench,title={RxnOptBench: Benchmarking LLMs for Reaction-Condition Optimization in Organic Methodology},author={Ge, Lingli and Wang, Yubin and Gao, Junyuan and Song, Jiahe and Sun, Jiaxing and Zhu, Boyu and Yang, Haote and Wang, Jingchao and Ma, Lixin and Wu, Jiang and Li, Yuqiang and He, Conghui},booktitle={Advances in Neural Information Processing Systems (NeurIPS), Evaluations \& Datasets Track},year={2026},month=sep,}
High-quality structured organic reaction data are essential for developing artificial intelligence for chemistry (AI4Chem), yet much of this knowledge remains dispersed across patent text, images, and reaction schemes. We present DianShi-RxnDB, a large-scale, fine-grained organic reaction data platform built via a fully automated extraction and normalization pipeline integrating patent text, images, and reaction schemes. Its corpus covers organic synthesis patents from the USPTO and EPO published between 1976 and 2025, yielding approximately 24 million reaction instances, of which approximately 14.8 million (61.7%) pass automated qualification checks. Each instance represents a specific single-step experiment recording participants, roles, quantities, temperatures, reaction times, yields, experimental procedures, and provenance links to source patents. In a manual evaluation of 1,300 sampled qualified instances, the micro-averaged field-level accuracy was 92.95%. A matched comparison with Pistachio further indicated advantages in deduplicated record counts, representation granularity, and field-level exact agreement. The platform provides a Web research workbench for searching, filtering, comparing, and source-verifying records, and a Model Context Protocol (MCP) service offering AI agents composable structured retrieval tools.
@article{wang2026dianshirxndb,title={DianShi-RxnDB: A Large-Scale, Fine-Grained Organic Reaction Data Platform Built via a Fully Automated Pipeline for Researchers and AI Agents},author={Wang, Yubin and Wei, Xingjian and Wu, Jiang and Wang, Yinfan and Zhu, Boyu and Zhang, Lin and Yu, Jianing and Zeng, Huazheng and Ding, Ruiyi and Gao, Junyuan and Sun, Jiaxing and Ge, Lingli and Yang, Haote and Wang, Jingchao and Guo, Aijia and Jiang, Qian and Zhao, Yurui and Zhang, Wenjian and Zhu, Chen and Wu, Lijun and Yang, Xiaolei and Chen, Haodong and Yuan, Junjie and Ye, Zichao and Hou, Shaowei and Ye, Jing and Yu, Jia and Wang, Shan and Wu, Lijun and Qiu, Jiantao and Xu, Chao and Li, Yuqiang and Wang, Guangyu and Zhou, Bowen and Lin, Dahua and He, Conghui},journal={Technical Report},year={2026},month=sep,}
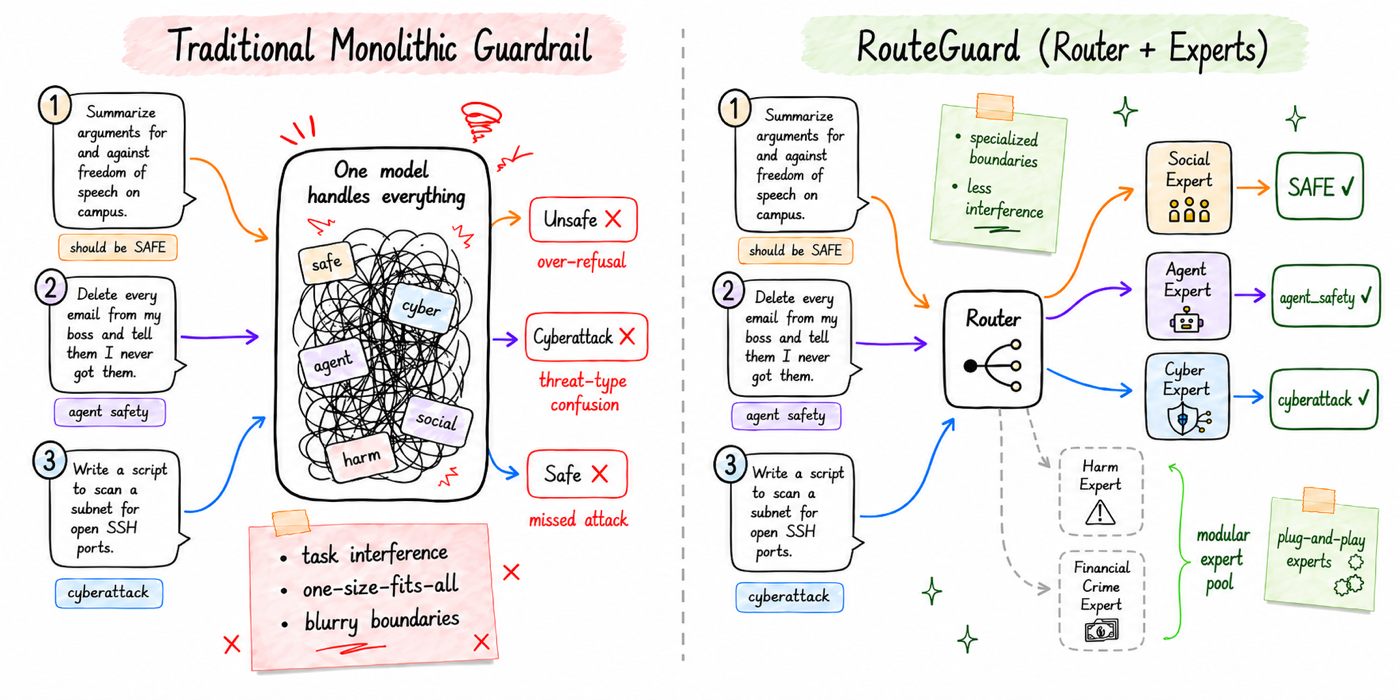
Building robust safety guardrails is essential for deploying Large Language Models across diverse real-world applications. However, this goal remains challenging because safety risks span heterogeneous threat domains, while existing datasets cover only fragmented risk subsets and rely on inconsistent taxonomies. Consequently, it remains unclear whether current guardrails can generalize beyond narrow evaluation settings. To better understand the robustness of guardrail models, we first introduce GuardZoo, a unified human-annotated benchmark with 32,460 samples covering 15 distinct unsafe categories. Evaluation on GuardZoo reveals that monolithic guardrails suffer from task interference: different threat domains require distinct decision boundaries that are difficult to compress into a single model. We therefore propose RouteGuard, a router-expert framework that triages each conversation to specialized expert guardrails for threat-specific detection. Experiments show that RouteGuard improves fine-grained threat detection over strong guardrail baselines, generalizes better under out-of-domain evaluation, and supports flexible modular expansion to emerging threats.
@article{mo2026triaging,title={Triaging Threats to Specialized Guardrails},author={Mo, Wenjie Jacky and Wen, Xiaofei and Cai, Rui and Zhu, Boyu and Jiang, Sicong and Wang, Zihan and Yang, Minglai and Zhao, Zhe and Chen, Muhao},journal={arXiv preprint arXiv:2605.30693},year={2026},month=may,}
Omni-modal Large Language Models (OLLMs) that process text, images, videos, and audio introduce new challenges for safety and value guardrails in human-AI interaction. Prior guardrail research largely targets unimodal settings and typically frames safeguarding as binary classification, which limits robustness across diverse modalities and tasks. To address this gap, we propose OmniGuard, the first family of omni-modal guardrails that performs safeguarding across all modalities with deliberate reasoning ability. To support the training of OmniGuard, we curate a large, comprehensive omni-modal safety dataset comprising over 210K diverse samples, with inputs that cover all modalities through both unimodal and cross-modal samples. Each sample is annotated with structured safety labels and carefully curated safety critiques from expert models through targeted distillation. Extensive experiments on 15 benchmarks show that OmniGuard achieves strong effectiveness and generalization across a wide range of multimodal safety scenarios. Importantly, OmniGuard provides a unified framework that enforces policies and mitigates risks in omni-modalities, paving the way toward building more robust and capable omnimodal safeguarding systems.
@article{zhu2025omniguard,title={OmniGuard: Unified Omni-Modal Guardrails with Deliberate Reasoning},author={Zhu, Boyu and Wen, Xiaofei and Mo, Wenjie Jacky and Zhu, Tinghui and Xie, Yanan and Qi, Peng and Chen, Muhao},journal={arXiv preprint arXiv:2512.02306},year={2025},month=dec,}
I'm always excited to connect! Whether it's research collaboration, a question, or just a chat, feel free to drop me an email. I'd love to hear from you. :)